
使用Accelerate库在多GPU上进行LLM推理
本篇文章给大家分享《使用Accelerate库在多GPU上进行LLM推理》,覆盖了科技周边的常见基础知识,其实一个语言的全部知识点一篇文章是不可能说完的,但希望通过这些问题,让读者对自己的掌握程度有一定的认识(B 数),从而弥补自己的不足,更好的掌握它。
大型语言模型(llm)已经彻底改变了自然语言处理领域。随着这些模型在规模和复杂性上的增长,推理的计算需求也显著增加。为了应对这一挑战利用多个gpu变得至关重要。
因此,这篇文章将在多个GPU上同时进行推理,内容主要包括:介绍Accelerate库、简单的方法和工作代码示例,以及使用多个GPU进行性能基准测试
本文将使用多个3090将llama2-7b的推理扩展在多个GPU上
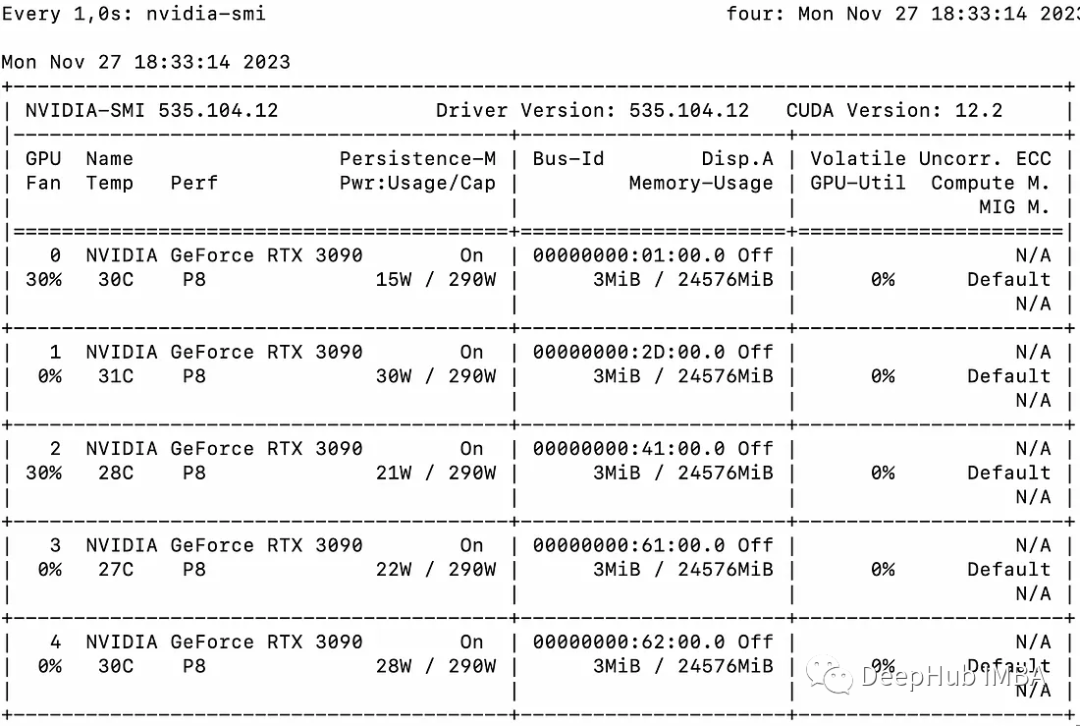
基本示例
我们首先介绍一个简单的示例来演示使用Accelerate进行多gpu“消息传递”。
from accelerate import Accelerator from accelerate.utils import gather_object accelerator = Accelerator() # each GPU creates a string message=[ f"Hello this is GPU {accelerator.process_index}" ] # collect the messages from all GPUs messages=gather_object(message) # output the messages only on the main process with accelerator.print() accelerator.print(messages)输出如下:
['Hello this is GPU 0', 'Hello this is GPU 1', 'Hello this is GPU 2', 'Hello this is GPU 3', 'Hello this is GPU 4']
多GPU推理
下面是一个简单的、非批处理的推理方法。代码很简单,因为Accelerate库已经帮我们做了很多工作,我们直接使用就可以:
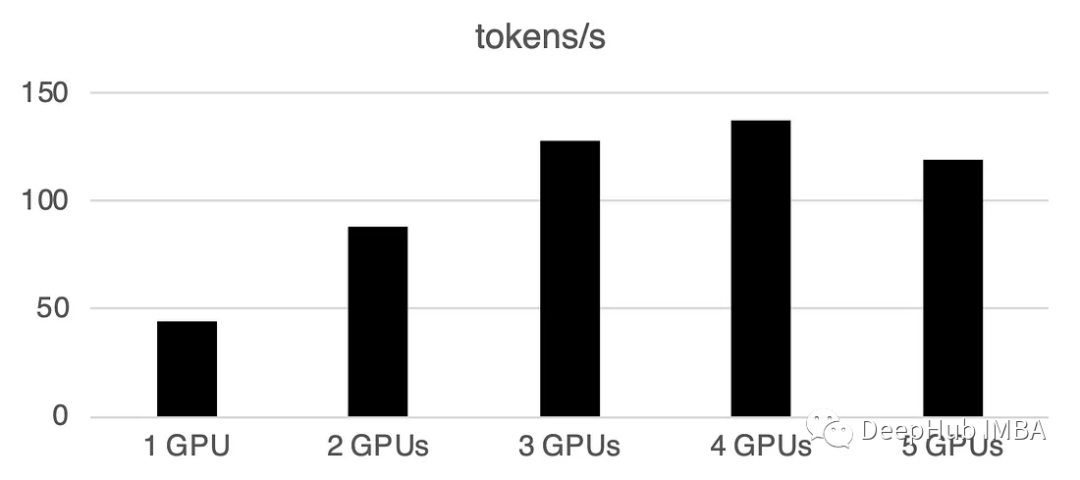
from accelerate import Accelerator from accelerate.utils import gather_object from transformers import AutoModelForCausalLM, AutoTokenizer from statistics import mean import torch, time, json accelerator = Accelerator() # 10*10 Prompts. Source: https://www.penguin.co.uk/articles/2022/04/best-first-lines-in-books prompts_all=["The King is dead. Long live the Queen.","Once there were four children whose names were Peter, Susan, Edmund, and Lucy.","The story so far: in the beginning, the universe was created.","It was a bright cold day in April, and the clocks were striking thirteen.","It is a truth universally acknowledged, that a single man in possession of a good fortune, must be in want of a wife.","The sweat wis lashing oafay Sick Boy; he wis trembling.","124 was spiteful. Full of Baby's venom.","As Gregor Samsa awoke one morning from uneasy dreams he found himself transformed in his bed into a gigantic insect.","I write this sitting in the kitchen sink.","We were somewhere around Barstow on the edge of the desert when the drugs began to take hold.", ] * 10 # load a base model and tokenizer model_path="models/llama2-7b" model = AutoModelForCausalLM.from_pretrained(model_path,device_map={"": accelerator.process_index},torch_dtype=torch.bfloat16, ) tokenizer = AutoTokenizer.from_pretrained(model_path) # sync GPUs and start the timer accelerator.wait_for_everyone() start=time.time() # divide the prompt list onto the available GPUs with accelerator.split_between_processes(prompts_all) as prompts:# store output of generations in dictresults=dict(outputs=[], num_tokens=0) # have each GPU do inference, prompt by promptfor prompt in prompts:prompt_tokenized=tokenizer(prompt, return_tensors="pt").to("cuda")output_tokenized = model.generate(**prompt_tokenized, max_new_tokens=100)[0] # remove prompt from output output_tokenized=output_tokenized[len(prompt_tokenized["input_ids"][0]):] # store outputs and number of tokens in result{}results["outputs"].append( tokenizer.decode(output_tokenized) )results["num_tokens"] += len(output_tokenized) results=[ results ] # transform to list, otherwise gather_object() will not collect correctly # collect results from all the GPUs results_gathered=gather_object(results) if accelerator.is_main_process:timediff=time.time()-startnum_tokens=sum([r["num_tokens"] for r in results_gathered ]) print(f"tokens/sec: {num_tokens//timediff}, time {timediff}, total tokens {num_tokens}, total prompts {len(prompts_all)}")使用多个gpu会导致一些通信开销:性能在4个gpu时呈线性增长,然后在这种特定设置中趋于稳定。当然这里的性能取决于许多参数,如模型大小和量化、提示长度、生成的令牌数量和采样策略,所以我们只讨论一般的情况
1 GPU: 44个token /秒,时间:225.5s
2个GPU:每秒处理88个token,总共用时112.9秒
3个GPU:每秒处理128个令牌,总共耗时77.6秒
4 gpu: 137个token /秒,时间:72.7s
5个gpu:每秒处理119个token,总共需要83.8秒的时间
在多GPU上进行批处理
现实世界中,我们可以使用批处理推理来加快速度。这会减少GPU之间的通讯,加快推理速度。我们只需要增加prepare_prompts函数将一批数据而不是单条数据输入到模型即可:
from accelerate import Accelerator from accelerate.utils import gather_object from transformers import AutoModelForCausalLM, AutoTokenizer from statistics import mean import torch, time, json accelerator = Accelerator() def write_pretty_json(file_path, data):import jsonwith open(file_path, "w") as write_file:json.dump(data, write_file, indent=4) # 10*10 Prompts. Source: https://www.penguin.co.uk/articles/2022/04/best-first-lines-in-books prompts_all=["The King is dead. Long live the Queen.","Once there were four children whose names were Peter, Susan, Edmund, and Lucy.","The story so far: in the beginning, the universe was created.","It was a bright cold day in April, and the clocks were striking thirteen.","It is a truth universally acknowledged, that a single man in possession of a good fortune, must be in want of a wife.","The sweat wis lashing oafay Sick Boy; he wis trembling.","124 was spiteful. Full of Baby's venom.","As Gregor Samsa awoke one morning from uneasy dreams he found himself transformed in his bed into a gigantic insect.","I write this sitting in the kitchen sink.","We were somewhere around Barstow on the edge of the desert when the drugs began to take hold.", ] * 10 # load a base model and tokenizer model_path="models/llama2-7b" model = AutoModelForCausalLM.from_pretrained(model_path,device_map={"": accelerator.process_index},torch_dtype=torch.bfloat16, ) tokenizer = AutoTokenizer.from_pretrained(model_path) tokenizer.pad_token = tokenizer.eos_token # batch, left pad (for inference), and tokenize def prepare_prompts(prompts, tokenizer, batch_size=16):batches=[prompts[i:i + batch_size] for i in range(0, len(prompts), batch_size)]batches_tok=[]tokenizer.padding_side="left" for prompt_batch in batches:batches_tok.append(tokenizer(prompt_batch, return_tensors="pt", padding='longest', truncatinotallow=False, pad_to_multiple_of=8,add_special_tokens=False).to("cuda") )tokenizer.padding_side="right"return batches_tok # sync GPUs and start the timer accelerator.wait_for_everyone() start=time.time() # divide the prompt list onto the available GPUs with accelerator.split_between_processes(prompts_all) as prompts:results=dict(outputs=[], num_tokens=0) # have each GPU do inference in batchesprompt_batches=prepare_prompts(prompts, tokenizer, batch_size=16) for prompts_tokenized in prompt_batches:outputs_tokenized=model.generate(**prompts_tokenized, max_new_tokens=100) # remove prompt from gen. tokensoutputs_tokenized=[ tok_out[len(tok_in):] for tok_in, tok_out in zip(prompts_tokenized["input_ids"], outputs_tokenized) ] # count and decode gen. tokens num_tokens=sum([ len(t) for t in outputs_tokenized ])outputs=tokenizer.batch_decode(outputs_tokenized) # store in results{} to be gathered by accelerateresults["outputs"].extend(outputs)results["num_tokens"] += num_tokens results=[ results ] # transform to list, otherwise gather_object() will not collect correctly # collect results from all the GPUs results_gathered=gather_object(results) if accelerator.is_main_process:timediff=time.time()-startnum_tokens=sum([r["num_tokens"] for r in results_gathered ]) print(f"tokens/sec: {num_tokens//timediff}, time elapsed: {timediff}, num_tokens {num_tokens}")可以看到批处理会大大加快速度。
需要重写的内容是:1个GPU:520个令牌/秒,时间:19.2秒
两张GPU的算力为每秒900个代币,计算时间为11.1秒
3 gpu: 1205个token /秒,时间:8.2s
四张GPU:1655个令牌/秒,所需时间为6.0秒
5个GPU: 每秒1658个令牌,时间:6.0秒

总结
截止到本文为止,llama.cpp,ctransformer还不支持多GPU推理,好像llama.cpp在6月有个多GPU的merge,但是我没看到官方更新,所以这里暂时确定不支持多GPU。如果有小伙伴确认可以支持多GPU请留言。
huggingface的Accelerate包则为我们使用多GPU提供了一个很方便的选择,使用多个GPU推理可以显着提高性能,但gpu之间通信的开销随着gpu数量的增加而显著增加。
理论要掌握,实操不能落!以上关于《使用Accelerate库在多GPU上进行LLM推理》的详细介绍,大家都掌握了吧!如果想要继续提升自己的能力,那么就来关注golang学习网公众号吧!
 只有特斯拉和长安启源数智AI电驱能够实现10层绕组的壮举?解读长安启源数智AI电驱(下)
- 上一篇
- 只有特斯拉和长安启源数智AI电驱能够实现10层绕组的壮举?解读长安启源数智AI电驱(下)
- 下一篇
- 9999 元,星纪魅族旗舰 AR 眼镜 MYVU Discovery 发布
-
- 科技周边 · 人工智能 | 1天前 |
- vLLM 连续批处理下的显存与吞吐取舍
- 209浏览 收藏
-
- 科技周边 · 人工智能 | 1天前 |
- Reranker 接入后如何控制检索延迟预算
- 113浏览 收藏
-
- 科技周边 · 人工智能 | 1天前 |
- Embedding 向量维度变化时的索引迁移方案
- 429浏览 收藏
-
- 科技周边 · 人工智能 | 1天前 |
- Agent 轨迹评测区分工具错误与模型错误
- 239浏览 收藏
-
- 科技周边 · 人工智能 | 1天前 |
- MCP 资源与工具描述的缓存更新策略
- 313浏览 收藏
-
- 科技周边 · 人工智能 | 1天前 |
- MCP 服务端授权范围与会话隔离的配置
- 161浏览 收藏
-
- 科技周边 · 人工智能 | 1天前 |
- MCP 工具结果分页与长列表截断的设计
- 486浏览 收藏
-
- 科技周边 · 人工智能 | 1天前 | 人工智能 · chat template apply_chat_template AI tokenizer 多模型消息格式
- AI tokenizer chat template 统一多模型消息格式
- 154浏览 收藏
-

- 前端进阶之JavaScript设计模式
- 设计模式是开发人员在软件开发过程中面临一般问题时的解决方案,代表了最佳的实践。本课程的主打内容包括JS常见设计模式以及具体应用场景,打造一站式知识长龙服务,适合有JS基础的同学学习。
- 543次学习
-

- GO语言核心编程课程
- 本课程采用真实案例,全面具体可落地,从理论到实践,一步一步将GO核心编程技术、编程思想、底层实现融会贯通,使学习者贴近时代脉搏,做IT互联网时代的弄潮儿。
- 516次学习
-

- 简单聊聊mysql8与网络通信
- 如有问题加微信:Le-studyg;在课程中,我们将首先介绍MySQL8的新特性,包括性能优化、安全增强、新数据类型等,帮助学生快速熟悉MySQL8的最新功能。接着,我们将深入解析MySQL的网络通信机制,包括协议、连接管理、数据传输等,让
- 500次学习
-

- JavaScript正则表达式基础与实战
- 在任何一门编程语言中,正则表达式,都是一项重要的知识,它提供了高效的字符串匹配与捕获机制,可以极大的简化程序设计。
- 487次学习
-

- 从零制作响应式网站—Grid布局
- 本系列教程将展示从零制作一个假想的网络科技公司官网,分为导航,轮播,关于我们,成功案例,服务流程,团队介绍,数据部分,公司动态,底部信息等内容区块。网站整体采用CSSGrid布局,支持响应式,有流畅过渡和展现动画。
- 485次学习
-

- PubMedQA
- 深入了解PubMedQA生物医学问答数据集,涵盖其核心功能、使用方法及在临床决策、药物研发等场景的应用,助力提升NLP模型性能。
- 424次使用
-

- H2O EvalGPT
- H2O EvalGPT是H2O.ai推出的开源LLM评估平台,提供详细的大模型性能排行榜、行业特定基准测试及A/B测试功能,助您快速选择最适合项目的高性能大语言模型。
- 504次使用
-

- LMArena
- LMArena是加州大学伯克利分校推出的AI模型匿名评测平台。通过盲测投票机制,用户可对比不同大模型回答并生成实时排行榜,助力开发者优化模型及用户选择最佳AI工具。
- 512次使用
-

- HELM
- 深入了解斯坦福推出的HELM(Holistic Evaluation of Language Models)大模型评测体系。本文解析其核心功能、安装配置步骤及应用场景,涵盖准确性、公平性、鲁棒性等多维度指标,助力开发者全面优化语言模型性能。
- 460次使用
-

- MMBench
- MMBench是由上海人工智能实验室等机构联合推出的多模态基准测试平台,提供细粒度能力评估、大规模数据集及VLMEvalKit工具。本文详细介绍其核心功能、安装使用方法及应用场景,助力开发者全面评估多模态模型性能。
- 289次使用
-
- 本地大模型反复输出同一句话怎么调整生成参数
- 2026-09-06 501浏览
-
- Python 调用大模型时如何用结构化输出校验 JSON:从解析失败到可重试
- 2026-08-29 501浏览
-
- AI写作工具免费版安装教程(含豆包Clawdbot)
- 2026-05-30 501浏览
-
- WPS AI能自动生成PPT吗?输入主题一键制作演示文稿
- 2026-05-27 501浏览
-
- Canva手机闪退解决方法及适配指南
- 2026-05-25 501浏览


